Have the AI developed app checked

AI developed Have the app checked

Have you built an app with Lovable, ChatGPT/Codex, Claude Code, Cursor or Vibe Coding?
We check code quality, architecture, security and performance and give you a clear assessment of whether you should continue building, launching or improving.

  • Short report within 48 h
  • independently evaluated
  • verified by real developers

Who can Check AI-generated code?

AI-generated code is checked by an independent software agency with experience in architecture, security and operations. Authentication, authorization, database access, secrets, input validation, dependencies, testing, deployment and maintainability are checked. The goal is to get a clear assessment of whether you should continue building, launching or making improvements. CodeGuides checks apps from Lovable, Claude Code, ChatGPT/Codex, Cursor and other tools and provides a prioritized action plan.

Check or make productive? An audit identifies risks and measures. The subsequent fixing, deployment and operation is a separate service: Make AI prototype ready for production. For a formal, independent assessment see Software reports.

What is behind searches such as "AI app review Reddit" or "ChatGPT app review“?

Searches with modifiers such as Reddit, forum, review or experiences usually do not signal demand for another sales page, but for real risk information. Teams want to know whether an app built with Lovable, Claude Code, ChatGPT/Codex or Cursor is safe enough for real users. A good answer names typical weaknesses, explains review criteria and shows when an independent review makes sense. That is what this page is built for.

What questions are behind this?

Typical search patterns include "Lovable app security", "ChatGPT app review", "Cursor app production ready" or "AI generated code audit". The real question is almost always: can I trust this code before customers, investors or internal users access it?

Why not create a separate Reddit landing page?

An artificial page only for the Reddit modifier would be thin and not credible. A real, verifiable answer is better: security, authentication, database, tests, deployment and operations, the questions users would otherwise ask in forums.

Why AI-generated code needs an independent review

Lovable, Claude Code, ChatGPT/Codex, Cursor, Copilot and other AI assistants can produce working code, but they rarely cover security, architecture and operations. That makes an independent code review essential.

Vulnerabilities due to missing context

AI generates code that fits the prompt, not the overall architecture. Typical consequences: unprotected endpoints, SQL injection, insecure secrets management.

  • OWASP vulnerabilities in generated code
  • Hardcoded credentials and API keys
  • Missing authentication and authorization

Architecture without foresight

KI optimizes locally for the current prompt. Global architectural decisions, scalability and technical debt arise systematically.

  • Inconsistent database structure and API design
  • Copy-paste redundancy instead of abstraction
  • Unscalable patterns under load

Operation and quality are almost always lacking

No monitoring, no testing, no CI/CD: AI-generated apps often run blind. Errors only become visible in productive operation.

  • Lack of automated testing and coverage
  • No logging, no monitoring, no alerting
  • Manual deployments without a rollback strategy
Checkpoints · Review an AI app

What we specifically check for AI-developed apps

We evaluate all areas that AI assistants typically neglect with technical depth and clear prioritization.

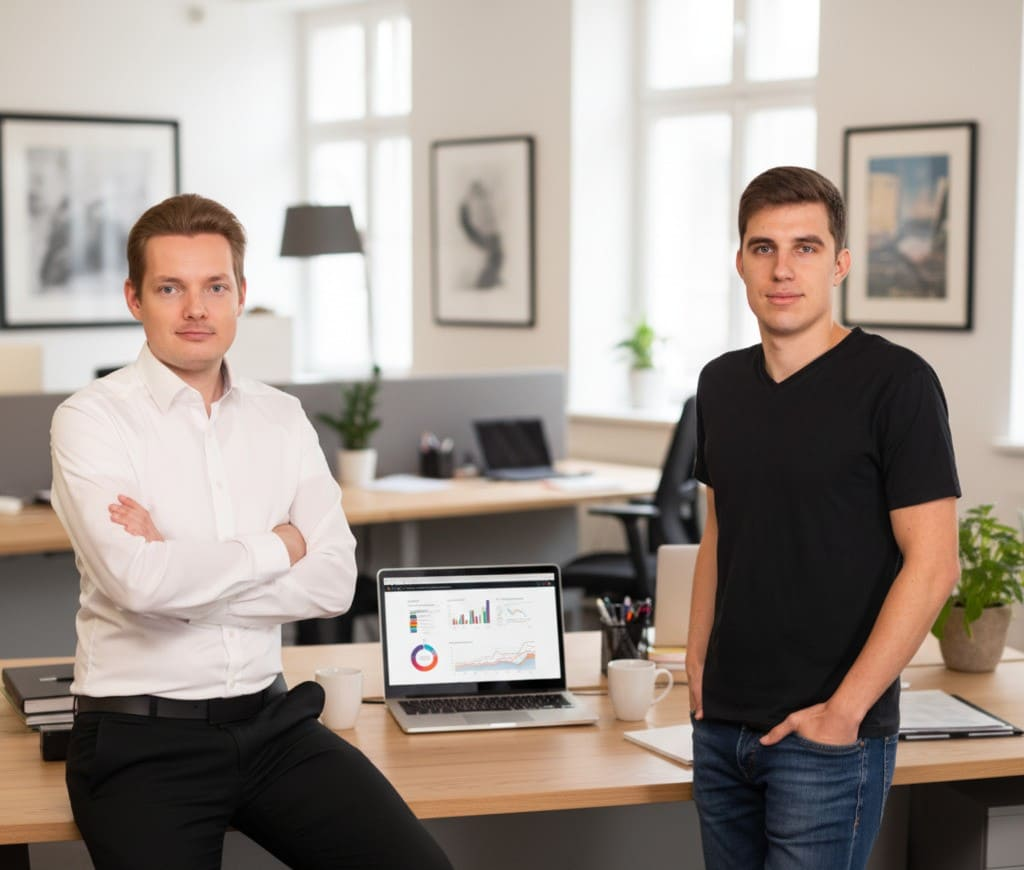
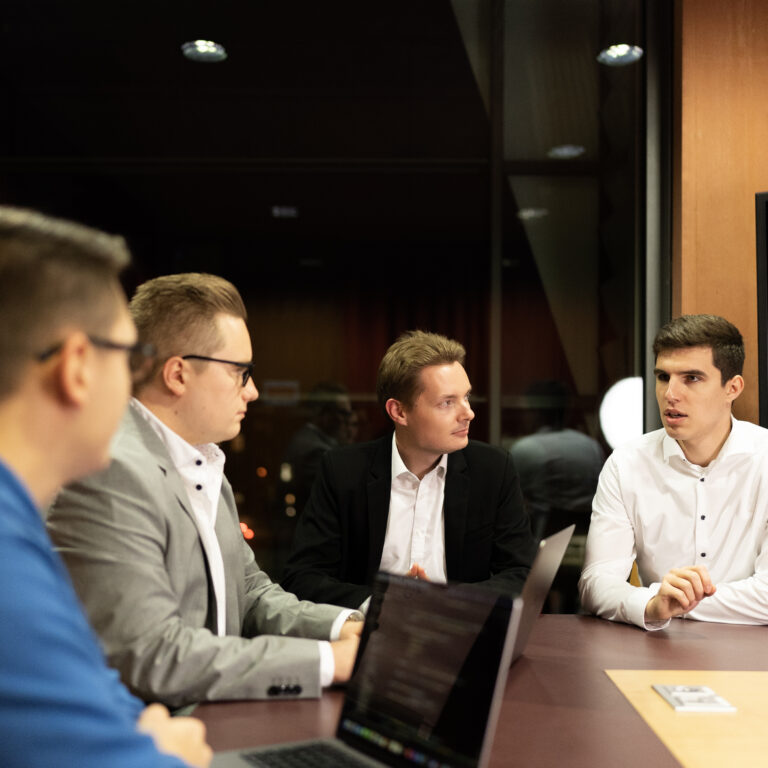
Franz Opitz and Alexander Hähnel reviewing an AI app

If necessary, we also check license risks for open source packages used, GDPR compliance of data processing as well as team and process risks. So ideal for Software Due Diligence before app purchase or investment.

Security & OWASP

Authentication, Authorization, Input Validation, SQL Injection, XSS, CSRF, Secrets Management and OWASP Top 10.

Code & Architecture

Structure, dependencies, design patterns, redundancies, technical debt and maintainability of the AI-generated code.

Database & API

Schema consistency, N+1 queries, index strategy, API design, versioning and error handling.

Operation & Performance

Logging, monitoring, CI/CD, deployment strategy, load testing, caching and resiliency.

Testing & Quality

Test coverage, unit and integration testing, linter configuration and code review process.

Scalability

Architectural decisions under load, database connections, queue management and cloud readiness.

Lovable, Claude Code, ChatGPT/Codex & Co.: What we check for each tool

Every AI tool comes with typical vulnerability patterns. We know them and specifically check what goes wrong with Lovable, Claude Code, ChatGPT/Codex, Cursor or other tools.

Lovable

Have Lovable App checked

Lovable generates React apps with Supabase backend, fast, but with structural security risks.

  • Supabase keys in the frontend bundle
  • Row Level Security often not activated
  • No server-side input validation
  • Auth logic directly in the client
  • No rate limiting, no monitoring
Claude Code

Have Claude Code app checked

Claude Code generates readable code, but operations, testing and architecture in the overall context are typically missing.

  • Lack of automated tests
  • No CI/CD and no deployment setup
  • Architecture without scaling path
  • Inconsistent error handling
  • No monitoring and logging strategy
ChatGPT/Codex

Have the ChatGPT/Codex app checked

ChatGPT/Codex can generate quick app changes and complete features, with typical risks around context limits, authentication, error handling and database design.

  • Prompts without vollständigen Architekturkontext
  • Inconsistent auth and role logic
  • Database schema without indexes and constraints
  • Missing CORS and CSP configuration
  • No clear separation between dev and production
Cursor

Have the cursor app checked

Cursor works directly in the editor, but context window boundaries lead to inconsistencies across module boundaries.

  • Inconsistent error handling per file
  • Duplicate logic across module boundaries
  • Secrets in .env without validation
  • Vulnerabilities in file uploads
  • Missing integration tests
v0.dev / Copilot

v0, Copilot & other tools

v0.dev delivers UI code (React/Next.js), Copilot snippets, both without looking at the overall system or backend security.

  • No backend, just UI logic delivered
  • API keys passed on as prop drilling
  • Copilot snippets with outdated patterns
  • No state management strategy
  • XSS risks due to uncontrolled rendering
Replit Agent & others

Have other AI tools checked

Replit Agent, Devin, Windsurf, Gemini Code Assist and others: We know the typical patterns of each tool and check independently.

  • Replit: No production-ready deployment stack
  • Devin: Architecture decisions without review
  • Windsurf: Similar weaknesses to Cursor
  • Tool-independent: operation and testing are almost always missing
  • Mixed codebases (human + AI) can also be tested

Vibe coding apps and AI prototypes put into production safely

Many teams today develop quick prototypes and MVPs with Lovable, Claude Code, ChatGPT/Codex or Cursor, and then want to turn them into real products. We check what can be safely taken over and what must be rebuilt.

What is good enough for production?

We clearly distinguish between code that can be used in a stable manner and areas that need to be cleaned up before launch.

Prioritized action plan

You receive a concrete roadmap: what is critical, what is important, what can wait, with realistic effort estimates.

Optional: We take care of the stabilization

After the review, we can start implementing it straight away: security patches, architecture refactoring and production-ready infrastructure.

Clear numbers instead of vague assessments

Our AI code review provides reliable time periods, structured checkpoints and actionable recommendations.

48 h
Short report possible

Top risks and critical vulnerabilities in AI-generated code.

5-10 days
Full report

Deep analysis with architecture, security, operations and prioritized action plan.

6 levels
Security until operation

We check all areas that AI assistants systematically neglect.

NDA
Confidential & independent

We work confidentially, with NDA upon request. Results stay with you.

CodeGuides team doing code review

That's how it works AI App Review from us

Minimum coordination effort, maximum insights. We do not disrupt your operations and deliver usable results in clear time frames.

Each step has defined outputs and traceable progress. No guesswork about what we're doing.

Tag 1

Kickoff, target image and approaches

We clarify goals, tech stack, usage context and obtain repo access and infrastructure documentation.

Scope Ziele Accesses
Day 2-5

Analysis, security check & code review

Structured testing of code, architecture, security, database, API, tests and operations, especially for vulnerabilities typical of AI.

Code Security Architecture
Day 5-7

Results and action plan

Prioritized findings, risk assessment, effort estimation and recommendations, presented in a workshop or as a report.

Prioritization Measures Decision
Optional

Stabilization & further development

We will take care of the implementation upon request: security fixes, architecture refactoring, test setup, CI/CD setup.

Fixes Stabilization Roadmap

What you get as a result

Clear, usable results so that you can make an informed decision whether and how to further develop the app.

Short report (48 h)

Quick overview for urgent decisions or as a first reality check before the launch.

  • Executive Summary
  • Critical security risks with impact
  • Top 3 measures immediately
Full report

In-depth analysis with complete risk assessment, prioritization and concrete action plan.

  • Architecture and code evaluation
  • Security & Performance Review
  • Prioritized action plan with effort
Workshop & Umsetzung

Joint evaluation with team or management, can be transferred directly to implementation planning.

  • Results workshop with Q&A
  • PoC for critical topics
  • Optional stabilization sprints

Initial general reports usually cost between 1,000 and 2,500 €. The exact cost depends on complexity and desired depth. We will clarify the framework in the preliminary discussion.

For whom is the AI app review suitable?

If you want to use an AI-developed app productively or further develop it, you need clarity about the actual risks.

Good fit
  • The app was developed with Lovable, Claude Code, ChatGPT/Codex, Cursor, Copilot or similar tools
  • You want to bring a vibe coding app or an AI prototype into production
  • You are planning to invest in an AI-developed app
  • Your team has security concerns or doubts about the quality of the generated code
  • You want to hand over the app, sell it or have it used by external users
  • Your app mixes human-written and AI-generated code
No fit
  • You expect pure confirmation without technical criticism
  • No access to repo or infrastructure possible
  • Pure cost optimization with no interest in quality
  • No interest in concrete measures

FAQ: Have the AI developed app checked

Why should I have an AI-developed app checked?

AI-generated code often contains hidden security vulnerabilities, lack of error handling, and poor architectural decisions that become costly to operate. An independent code review provides clarity before you invest or go live.

What is Vibe Coding and what are the risks?

Vibe coding is the practice of developing an app almost entirely through prompts to AI assistants such as Cursor, Copilot or ChatGPT. The result can work, but often comes with critical risks: missing tests, SQL injection, unprotected API endpoints and unscalable architecture.

What do you check for an AI-developed app?

We review security (OWASP, Secrets, Auth), code quality and architecture, database structure, API design, error handling, test coverage, operability and scalability, and deliver a prioritized action plan.

What is the difference from a normal code review?

Our AI app review specializes in the typical vulnerabilities of AI-generated code: security vulnerabilities due to a lack of global context, architectural inconsistencies, copy-paste redundancies and a lack of operational fundamentals such as testing, CI/CD and monitoring.

How long does an AI code review take?

A short report with the most important risks is possible in 48 hours. A complete report with architectural analysis and action plan takes 5-10 working days depending on the scope.

What access do you need?

Usually repo access (e.g. GitHub, GitLab), infrastructure documentation and, if necessary, test access. We agree on the scope at kickoff and work confidentially.

How much does the AI App Review cost?

The exact costs depend on the complexity and desired accuracy of the report. As a rule, initial general reports from us cost between €1,000 and €2,500. We will clarify the specific framework in a free preliminary consultation.

Can I further develop the app or have it stabilized afterwards?

Yes. After the review, we can take care of stabilization, further development or complete conversion, including roadmap, security fixes and implementation sprints.

Is the review also suitable for an app that I want to buy or invest in?

Yes. Our AI app review provides a technical decision template for investors and buyers, with clear risks, cost implications and recommendations for evaluation.

Which AI tools can you consider in an app audit?

We review apps built with all common AI tools: Lovable, Claude Code, ChatGPT/Codex, Cursor, GitHub Copilot, v0.dev, Replit Agent and others. Each tool has typical weakness patterns that we consider deliberately during the review.

Can you have a Lovable app checked?

Yes. Lovable apps use React with Supabase backend, a pattern that presents clear security risks: Supabase keys in the frontend bundle, missing row level security, no server-side validation and auth logic directly in the client. We examine exactly these weak points and provide a prioritized action plan.

Can you have a Claude Code app checked?

Yes. Claude Code also has typical gaps: missing tests, no CI/CD setup, architectural decisions without overall context and operational fundamentals that were not part of the prompt. We check independently and show what is missing before productive operation.

Can you have a ChatGPT/Codex app checked?

Yes. ChatGPT/Codex apps and features are created quickly, but they often have gaps caused by missing full-system context: inconsistent auth, weak error handling, missing tests and no clear separation between development and production environments. We assess what must be rebuilt for production use.

Do you also check apps that were developed with multiple AI tools at the same time?

Yes. Many projects are created with a combination of e.g. B. Lovable for the frontend, Claude Code for backend logic and Copilot for individual functions. We check the entire code base regardless of the tool used, including inconsistencies in the interfaces.

How confidential is the report?

We work confidentially and will sign an NDA upon request. Results and code remain solely yours.

Another question that isn't answered here? Clarify in the appointment →

Why CodeGuides for the AI app review?

  • In-house team from Germany: You work with a permanent German team: no freelancers, no outsourcing risk.
  • ⌨️ Experts for complex projects: You benefit from specialists in architecture, app development, backend & QA, all from a single source.
  • 💲 Cost transparency & clear planning: Full transparency through minute-by-minute time recording, realistic roadmaps & reliable effort estimates.
Alexander Hähnel portrait
Alexander Hähnel
Managing Director, App and Software Development
Franz Opitz portrait
Franz Opitz
Managing Director, Automation and Cloud Deployment

Have the AI developed app checked: Book a preliminary consultation

About CodeGuides

CodeGuides is an app and AI agency from Germany for Flutter apps, custom software, AI automation and local AI infrastructure. Consulting and implementation come from a single source: We evaluate use cases technically, build the first pilot and scale it up to company-wide operation, GDPR-compliant and with hosting in Germany.

CodeGuides GmbH · Königs Wusterhausen On the market since 2019 100+ digital projects 100% in-house (DE) Consulting & implementation from a single source