Get an AI-developed app reviewed

AI-generated Have the app checked

Have you built an app with Lovable, ChatGPT/Codex, Claude Code, Cursor or Vibe Coding?
We check code quality, architecture, security and performance and give you a clear assessment of whether you should continue building, launching or improving.

  • Short report within 48 h
  • independently evaluated
  • verified by real developers

Who can Check AI-generated code?

An independent software agency with experience in architecture, security, and operations reviews AI-generated code. We check authentication, authorization, database access, secrets management, input validation, dependencies, testing, deployment, and maintainability. The goal is to give you a clear assessment of whether to continue building, launch, or make improvements. CodeGuides reviews apps built with Lovable, Claude Code, ChatGPT/Codex, Cursor, and other tools, then provides a prioritized action plan.

Review it or get it production-ready? A review identifies risks and recommended actions. Remediation, deployment, and ongoing operations are separate services: Take an AI prototype from review to production. For a formal, independent assessment see Software reports.

What is behind searches such as "AI app review Reddit" or "ChatGPT app review“?

Searches that include terms like Reddit, forum, review, or user experiences usually indicate a need for real information about risks, not another sales page. Teams want to know whether an app built with Lovable, Claude Code, ChatGPT/Codex, or Cursor is safe for real users. A useful answer identifies common weaknesses, explains the review criteria, and shows when an independent review makes sense. That’s what this page is designed to do.

What questions are behind this?

Common searches include “Lovable app security,” “ChatGPT app review,” “Cursor app production ready,” and “AI generated code audit.” The underlying question is almost always the same: Can I trust this code before customers, investors, or internal users access it?

Why not create a separate Reddit landing page?

A page created solely to target the term Reddit would be thin and unconvincing. A real, verifiable answer is more useful: address security, authentication, databases, testing, deployment, and operations—the questions people would otherwise ask in forums.

Why AI-generated code needs an independent review

Lovable, Claude Code, ChatGPT/Codex, Cursor, Copilot, and other AI assistants can produce working code, but they rarely account for security, architecture, and operations. That’s why an independent code review is essential.

Vulnerabilities due to missing context

AI generates code that fits the prompt, not the overall architecture. Typical consequences: unprotected endpoints, SQL injection, insecure secrets management.

  • OWASP vulnerabilities in generated code
  • Hardcoded credentials and API keys
  • Missing authentication and authorization

Architecture without foresight

AI optimizes locally for the current prompt. Architectural decisions, scalability issues and technical debt are recurring challenges.

  • Inconsistent database structure and API design
  • Copy-paste redundancy instead of abstraction
  • Unscalable patterns under load

Operation and quality are almost always lacking

Without monitoring, testing, or CI/CD, AI-generated apps often run without visibility. Issues may not become apparent until the app is in production.

  • Lack of automated testing and coverage
  • No logging, no monitoring, no alerting
  • Manual deployments without a rollback strategy
Review checkpoints for an AI app

What we specifically check for AI-developed apps

We evaluate all areas that AI assistants typically neglect with technical depth and clear prioritization.

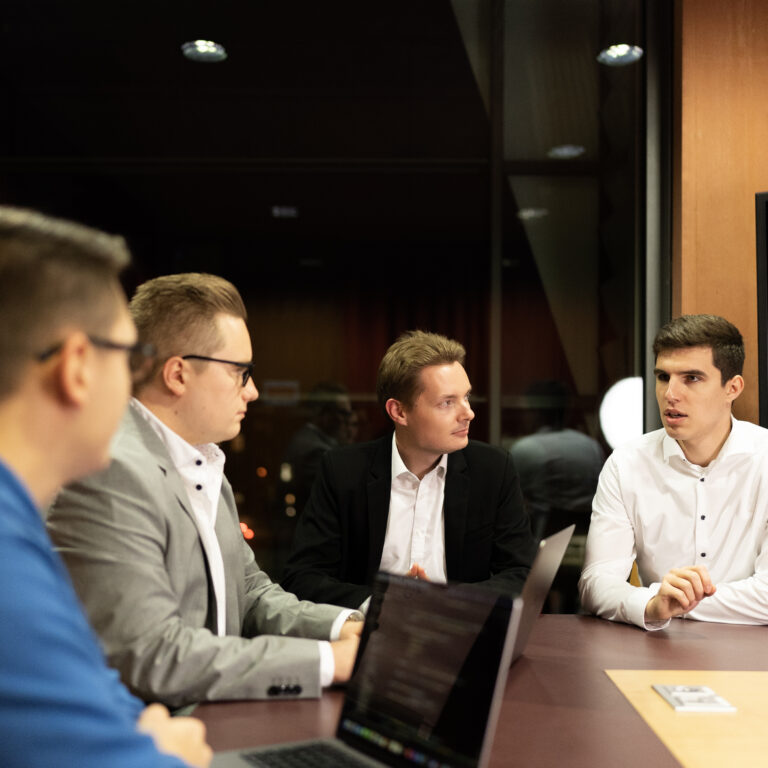
Franz Opitz and Alexander Hähnel reviewing an AI app

If needed, we also assess license risks in the open-source packages used, GDPR compliance in data processing, and team and process risks. This makes the review a good fit for Software Due Diligence before app purchase or investment.

Security & OWASP

Authentication, Authorization, Input Validation, SQL Injection, XSS, CSRF, Secrets Management and OWASP Top 10.

Code & Architecture

Structure, dependencies, design patterns, redundancies, technical debt and maintainability of the AI-generated code.

Database & API

Schema consistency, N+1 queries, index strategy, API design, versioning and error handling.

Operation & Performance

Logging, monitoring, CI/CD, deployment strategy, load testing, caching and resiliency.

Testing & Quality

Test coverage, unit and integration testing, linter configuration and code review process.

Scalability

Architectural decisions under load, database connections, queue management and cloud readiness.

Lovable, Claude Code, ChatGPT/Codex & Co.: What we check for each tool

Every AI tool has its own common vulnerability patterns. We know what to look for and check specifically for issues associated with Lovable, Claude Code, ChatGPT/Codex, Cursor, and other tools.

Lovable

Have Lovable app checked

Lovable quickly generates React apps with a Supabase backend, but this approach can introduce structural security risks.

  • Supabase keys in the frontend bundle
  • Row Level Security often not activated
  • No server-side input validation
  • Auth logic directly in the client
  • No rate limiting, no monitoring
Claude Code

Have Claude Code app checked

Claude Code generates readable code, but testing, operations, and architecture across the broader system are often overlooked.

  • Lack of automated tests
  • No CI/CD and no deployment setup
  • Architecture without scaling path
  • Inconsistent error handling
  • No monitoring and logging strategy
ChatGPT/Codex

Have the ChatGPT/Codex app checked

ChatGPT/Codex can quickly generate app changes and complete features, but common risks include limited context, authentication issues, poor error handling, and database design problems.

  • Prompts without full architectural context
  • Inconsistent auth and role logic
  • Database schema without indexes and constraints
  • Missing CORS and CSP configuration
  • No clear separation between dev and production
Cursor

Have Your Cursor App Reviewed

Cursor works directly in the editor, but context-window limitations can lead to inconsistencies between modules.

  • Inconsistent error handling per file
  • Duplicate logic across module boundaries
  • Secrets in .env without validation
  • Vulnerabilities in file uploads
  • Missing integration tests
v0.dev / Copilot

v0, Copilot & other tools

v0.dev generates UI code (React/Next.js), while Copilot provides code snippets. Neither necessarily accounts for the overall system or backend security.

  • UI logic only—no backend
  • API keys exposed through prop drilling
  • Copilot snippets with outdated patterns
  • No state management strategy
  • XSS risks due to uncontrolled rendering
Replit Agent & others

Have other AI tools checked

Replit Agent, Devin, Windsurf, Gemini Code Assist, and other tools: we know the common patterns associated with each and review the code independently.

  • Replit: No production-ready deployment stack
  • Devin: Architecture decisions without review
  • Windsurf: Similar weaknesses to Cursor
  • Tool-independent: operation and testing are almost always missing
  • Mixed codebases (human + AI) can also be tested

Vibe coding apps and AI prototypes put into production safely

Many teams now use Lovable, Claude Code, ChatGPT/Codex, or Cursor to build quick prototypes and MVPs, then want to turn them into real products. We assess what can be safely reused and what must be rebuilt.

What’s ready for production?

We clearly distinguish code that can be used reliably from areas that need work before launch.

Prioritized action plan

You receive a concrete roadmap with realistic effort estimates: what’s critical, what matters, and what can wait.

Optional: We take care of the stabilization

After the review, we can start implementing it straight away: security patches, architecture refactoring and production-ready infrastructure.

Clear numbers instead of vague assessments

Our AI code review provides realistic timelines, structured checkpoints, and actionable recommendations.

48 h
Short report possible

Top risks and critical vulnerabilities in AI-generated code.

5-10 days
Full report

In-depth analysis of architecture, security, and operations, with a prioritized action plan.

6 levels
Security until operation

We check all areas that AI assistants systematically neglect.

NDA
Confidential & independent

We work confidentially and can sign an NDA upon request. The results are yours.

CodeGuides team doing code review

That's how it works AI App Review with us

Minimal coordination, maximum insight. We work without disrupting your operations and deliver actionable results within clearly defined time frames.

Each step has defined deliverables and measurable progress, so you always know what we’re doing.

Day 1

Kickoff, goals and access

We clarify your goals, tech stack, and use case, and gather access to the repository and infrastructure documentation.

Scope Goals Accesses
Day 2-5

Analysis, security check & code review

Structured testing of code, architecture, security, database, API, tests and operations, especially for vulnerabilities typical of AI.

Code Security Architecture
Day 5-7

Results and action plan

Prioritized findings, risk assessments, effort estimates, and recommendations, presented in a workshop or report.

Prioritization Measures Decision
Optional

Stabilization & further development

On request, we can implement the recommended changes, including security fixes, architecture refactoring, test setup, and CI/CD setup.

Fixes Stabilization Roadmap

What you get as a result

Clear, actionable results to help you decide whether and how to continue developing the app.

Short report (48 h)

A quick overview for time-sensitive decisions or an initial reality check before launch.

  • Executive Summary
  • Critical security risks with impact
  • Top 3 measures immediately
Full report

An in-depth analysis with a comprehensive risk assessment, prioritized findings, and a concrete action plan.

  • Architecture and code evaluation
  • Security & Performance Review
  • Prioritized action plan with effort
Workshop & implementation

A joint review with your team or management, ready to feed directly into implementation planning.

  • Results workshop with Q&A
  • PoC for critical topics
  • Optional stabilization sprints

Our initial general assessments typically cost between €1,000 to €2,500. The exact cost depends on complexity and desired depth. We will clarify the framework in the preliminary discussion.

Who it's for is the AI app review suitable?

If you plan to use or continue developing an app built with AI, you need a clear picture of the actual risks.

A good fit
  • The app was developed with Lovable, Claude Code, ChatGPT/Codex, Cursor, Copilot or similar tools
  • You want to bring a vibe coding app or an AI prototype into production
  • You are planning to invest in an AI-developed app
  • Your team has security concerns or doubts about the quality of the generated code
  • You want to hand over the app, sell it or have it used by external users
  • Your app mixes human-written and AI-generated code
Not a good fit
  • You expect pure confirmation without technical criticism
  • No access to repo or infrastructure possible
  • Pure cost optimization with no interest in quality
  • No interest in specific actions

FAQ: Reviewing an AI-developed app

Why should I get an app built with AI reviewed?

AI-generated code often contains hidden security vulnerabilities, inadequate error handling, and poor architectural decisions that can make the app costly to operate. An independent code review gives you clarity before you invest or launch.

What is Vibe Coding and what are the risks?

Vibe coding means building an app almost entirely through prompts to AI assistants such as Cursor, Copilot, or ChatGPT. The result may work, but often carries serious risks: missing tests, SQL injection, unprotected API endpoints, and an architecture that won’t scale.

What do you review in an app built with AI?

We review security (OWASP, secrets, and authentication), code quality and architecture, database structure, API design, error handling, test coverage, operability, and scalability. We then provide a prioritized action plan.

How is this different from a standard code review?

Our AI app review focuses on common vulnerabilities in AI-generated code: security gaps caused by limited system-wide context, architectural inconsistencies, redundant copied code, and missing operational essentials such as testing, CI/CD, and monitoring.

How long does an AI code review take?

A brief report covering the most important risks can be delivered in 48 hours. A full report with architectural analysis and an action plan takes 5–10 business days, depending on scope.

What access do you need?

We typically need repository access (for example, through GitHub or GitLab), infrastructure documentation, and, if necessary, test access. We agree on the scope at kickoff and work confidentially.

How much does an AI app review cost?

The cost depends on the complexity of the app and the level of detail you want in the report. Our initial general assessments typically cost between €1,000 and €2,500. We’ll discuss the scope in a free initial consultation.

Can I continue developing or stabilize the app after the review?

Yes. After the review, we can stabilize the app, continue its development, or rebuild it entirely. This can include a roadmap, security fixes, and implementation sprints.

Is the review suitable for an app I’m considering buying or investing in?

Yes. Our AI app review gives investors and buyers a technical basis for their decision, with clear risks, cost implications, and recommendations to inform their evaluation.

Which AI tools can you review as part of an app audit?

We review apps built with all common AI tools, including Lovable, Claude Code, ChatGPT/Codex, Cursor, GitHub Copilot, v0.dev, and Replit Agent. Each tool has common weaknesses that we specifically look for during the review.

Can you review an app built with Lovable?

Yes. Lovable apps use React with a Supabase backend, a combination that can pose clear security risks: Supabase keys exposed in the frontend bundle, missing row-level security, no server-side validation, and authentication logic running directly in the client. We check these specific vulnerabilities and provide a prioritized action plan.

Can you review an app built with Claude Code?

Yes. Claude Code projects can have common gaps: missing tests, no CI/CD setup, architectural decisions made without an understanding of the overall system, and operational essentials that weren’t covered in the prompt. We conduct an independent review and identify what’s missing before the app goes into production.

Can you review an app built with ChatGPT/Codex?

Yes. ChatGPT/Codex can quickly generate apps and features, but limited system-wide context can leave gaps: inconsistent authentication, weak error handling, missing tests, and no clear separation between development and production environments. We assess what needs to be rebuilt before the app is ready for production.

Do you also review apps built with multiple AI tools?

Yes. Many projects combine tools—for example, Lovable for the frontend, Claude Code for backend logic, and Copilot for individual functions. We review the entire codebase regardless of which tools were used, including inconsistencies between components.

How confidential is the report?

We work confidentially and will sign an NDA upon request. Results and code remain solely yours.

Another question that isn't answered here? Clarify in the appointment →

Why CodeGuides for an AI app review?

  • In-house team based in Germany: You work with a dedicated team in Germany—no freelancers or outsourcing.
  • ⌨️ Experts for complex projects: You benefit from specialists in architecture, app development, backend and QA, all working together.
  • 💲 Cost transparency & clear planning: Full transparency with minute-by-minute time tracking, realistic roadmaps and reliable estimates.
Alexander Hähnel portrait
Alexander Hähnel
Managing Director, App and Software Development
Franz Opitz portrait
Franz Opitz
Managing Director, Automation and Cloud Deployment

Get an AI-developed app reviewed: Book a preliminary consultation

About CodeGuides

CodeGuides develops apps for consumers and businesses, with a primary focus on B2C apps. Our in-house team in Germany provides product planning, Flutter development and long-term operations, alongside custom software, AI automation and local AI infrastructure.

CodeGuides GmbH · Königs Wusterhausen On the market since 2018 100+ digital projects 100% in-house (Germany) Consulting & implementation from a single source